
-
 ToolCanva
Canva Brush
Canva Research's vision-language model for design edits, from one line of copy to every slide in a deck. Live in Canva AI for Canva Pro subscribers.
For film: Changes pitch decks and title cards on request, keeping what you didn't ask to change.
Maker's page ↗ -
 AudioElevenLabs
SFX v3
New sound effects model in ElevenCreative and ElevenAPI that follows prompts describing several sounds at once.
For film: One prompt can build a layered scene: crowd, ball, then boos, with fewer artefacts.
Maker's page ↗ -
 LLMMistral AI
Mistral Large 4
Open weights for Mistral's 1-trillion-parameter multimodal model (text and image in, text out), on Hugging Face and the Mistral API.
Maker's page ↗ -
 VideoPika
Pika H3 Flex
Pika's post-trained MiniMax H3 video model with synced stereo audio, up to 12 image, video and audio references, and open weights.
For film: Five separate audio stems through the API, so dialogue and score mix separately.
Maker's page ↗
-
 LLMGoogle
Gemini 4 Carbon
Google's new frontier Gemini model for coding, cybersecurity and long tasks; access starts with selected cyber defence partners.
Maker's page ↗ -
 VideoSenseTime
SenseNova 6.8 Code2Video
Open 27B model that makes video by writing and fixing the code that draws each frame, aimed at motion graphics and explainers.
For film: Editable motion graphics and explainer clips as code, not photoreal footage.
Maker's page ↗
-
 LLMLiquid AI
LFM3
Open-weight family of small 2B-class models on one backbone: text, vision, audio, omni and decision models that run on phones and laptops.
For film: LFM3-Audio-2B transcribes, voices and translates speech in 18 languages on-device.
Maker's page ↗
-
 LLMOpenAI
GPT-6.1 Terra
Fast, cheaper GPT-6.1 model for visual reasoning, computer use and writing, with a 1.05M-token context; in ChatGPT Work, Codex and the API.
For film: Half the API price of GPT-5.6 Terra; tested on time-coded shot logs and video editing.
Maker's page ↗
-
LLMMoonshot AI
Kimi K3.1 Pro
First model in the K3.1 series, with a 1M-token context and a faster Highspeed variant; live in Kimi and the Kimi API, full weights promised by 4 Nov.
For film: Holds very long scripts and documents in one go; Moonshot cites gains in 3D creation.
Maker's page ↗
-
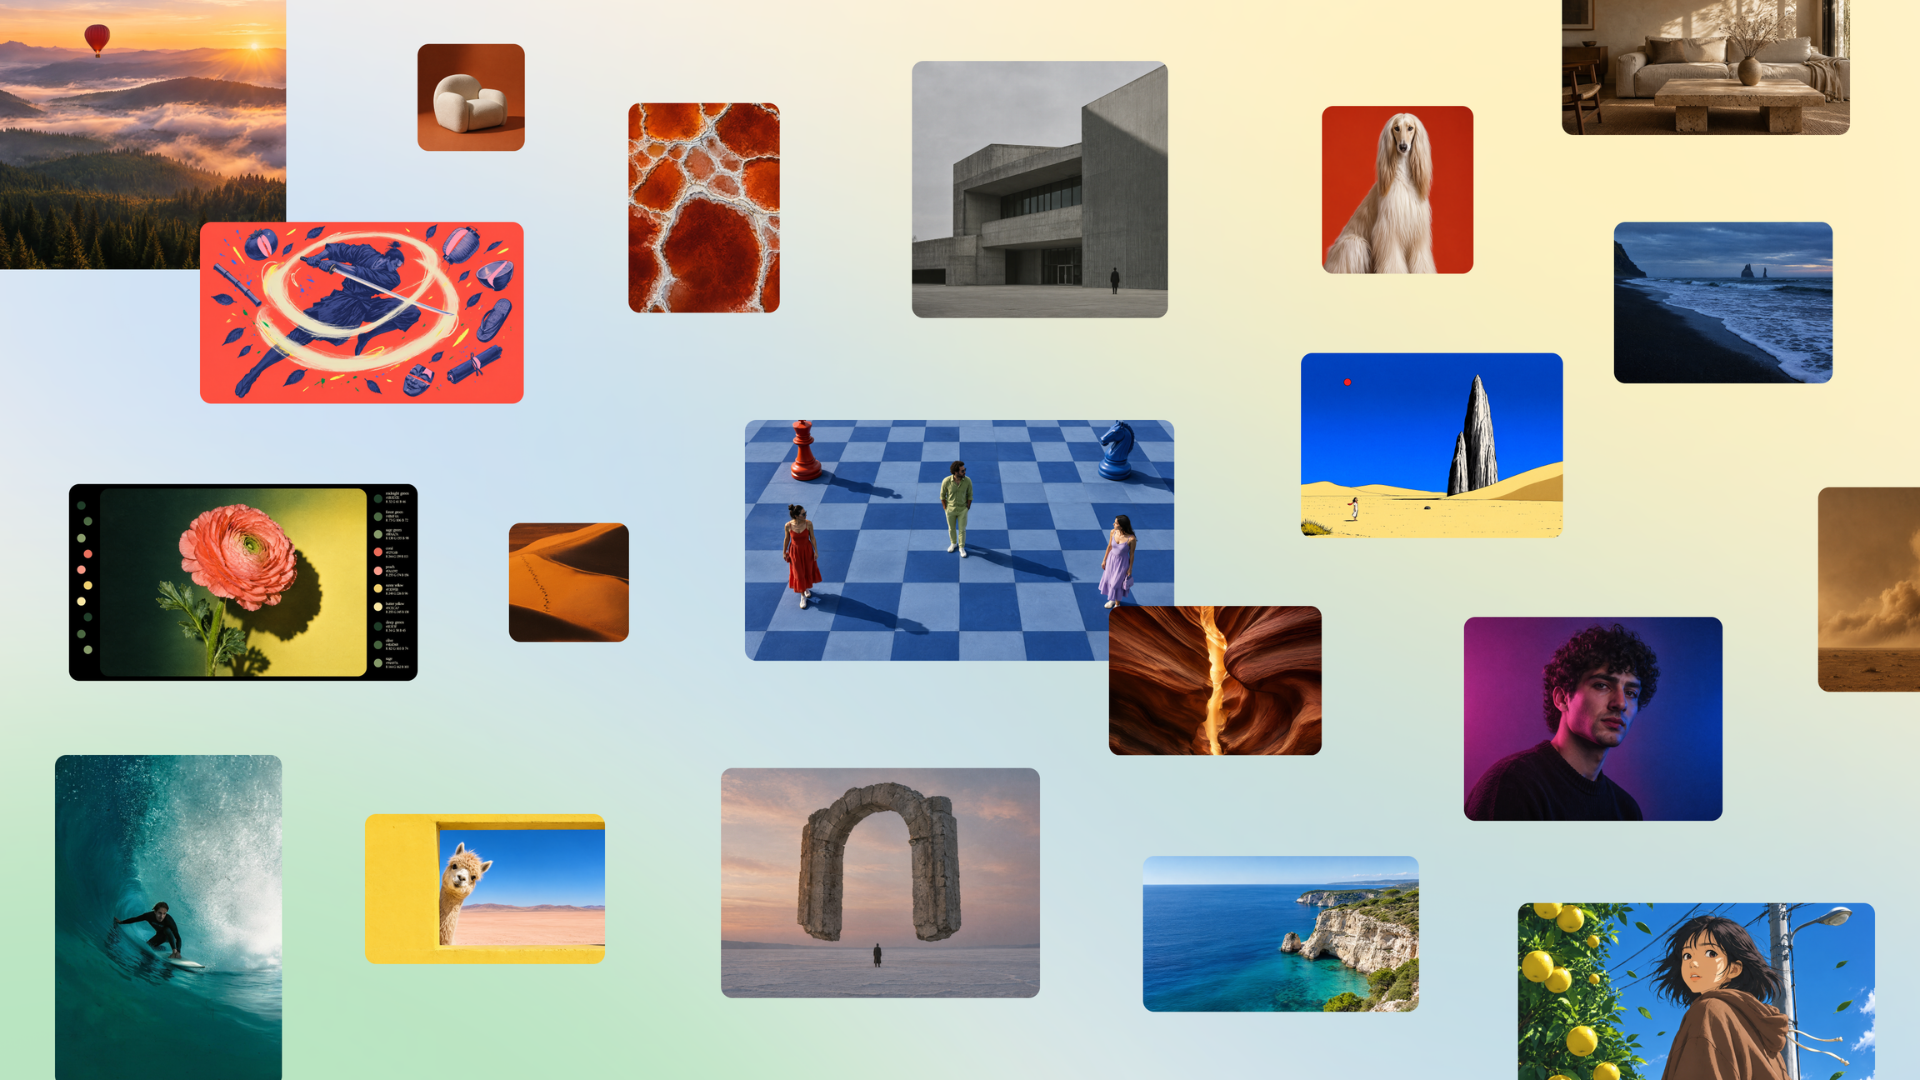 ImageCanva
Canva Craft
Canva's first in-house image model: plans the layout first, then renders up to 2K across more than 30 aspect ratios. In Canva and the public API.
For film: Planned layouts with legible text, useful for posters, title cards and pitch-deck stills.
Maker's page ↗
-

Hy-Nomas
Open-weight interactive video world model: steer each new segment with text and camera moves as it generates, 720 x 1280 at 24 fps.
For film: Change scenes, actions and camera mid-generation; an INT8 setup runs on one RTX 4090.
Maker's page ↗
-

Fibo 2.0
Open-weights image model that generates and edits in one, as Dev plus a 4-step Edit Turbo; non-commercial licence.
For film: Instruction edits keep identity, layout and lighting; trained only on licensed data.
Maker's page ↗ -
Eleven Realtime v1
New speech-to-speech models for voice agents: v1 Mini for natural chat at low cost, v1 Max for complex tasks.
For film: Mini is pitched for interactive characters, in 90+ languages with any library voice.
Maker's page ↗ -
 AudioMistral AI
Voxtral 3
New Voxtral speech family: Voxtral Small Transcribe 3, Voxtral Mini TTS 3 and a real-time voice agent SDK.
For film: Voices shift emotion and pace with context; Pro Voice adapts from 30 minutes of audio.
Maker's page ↗
-
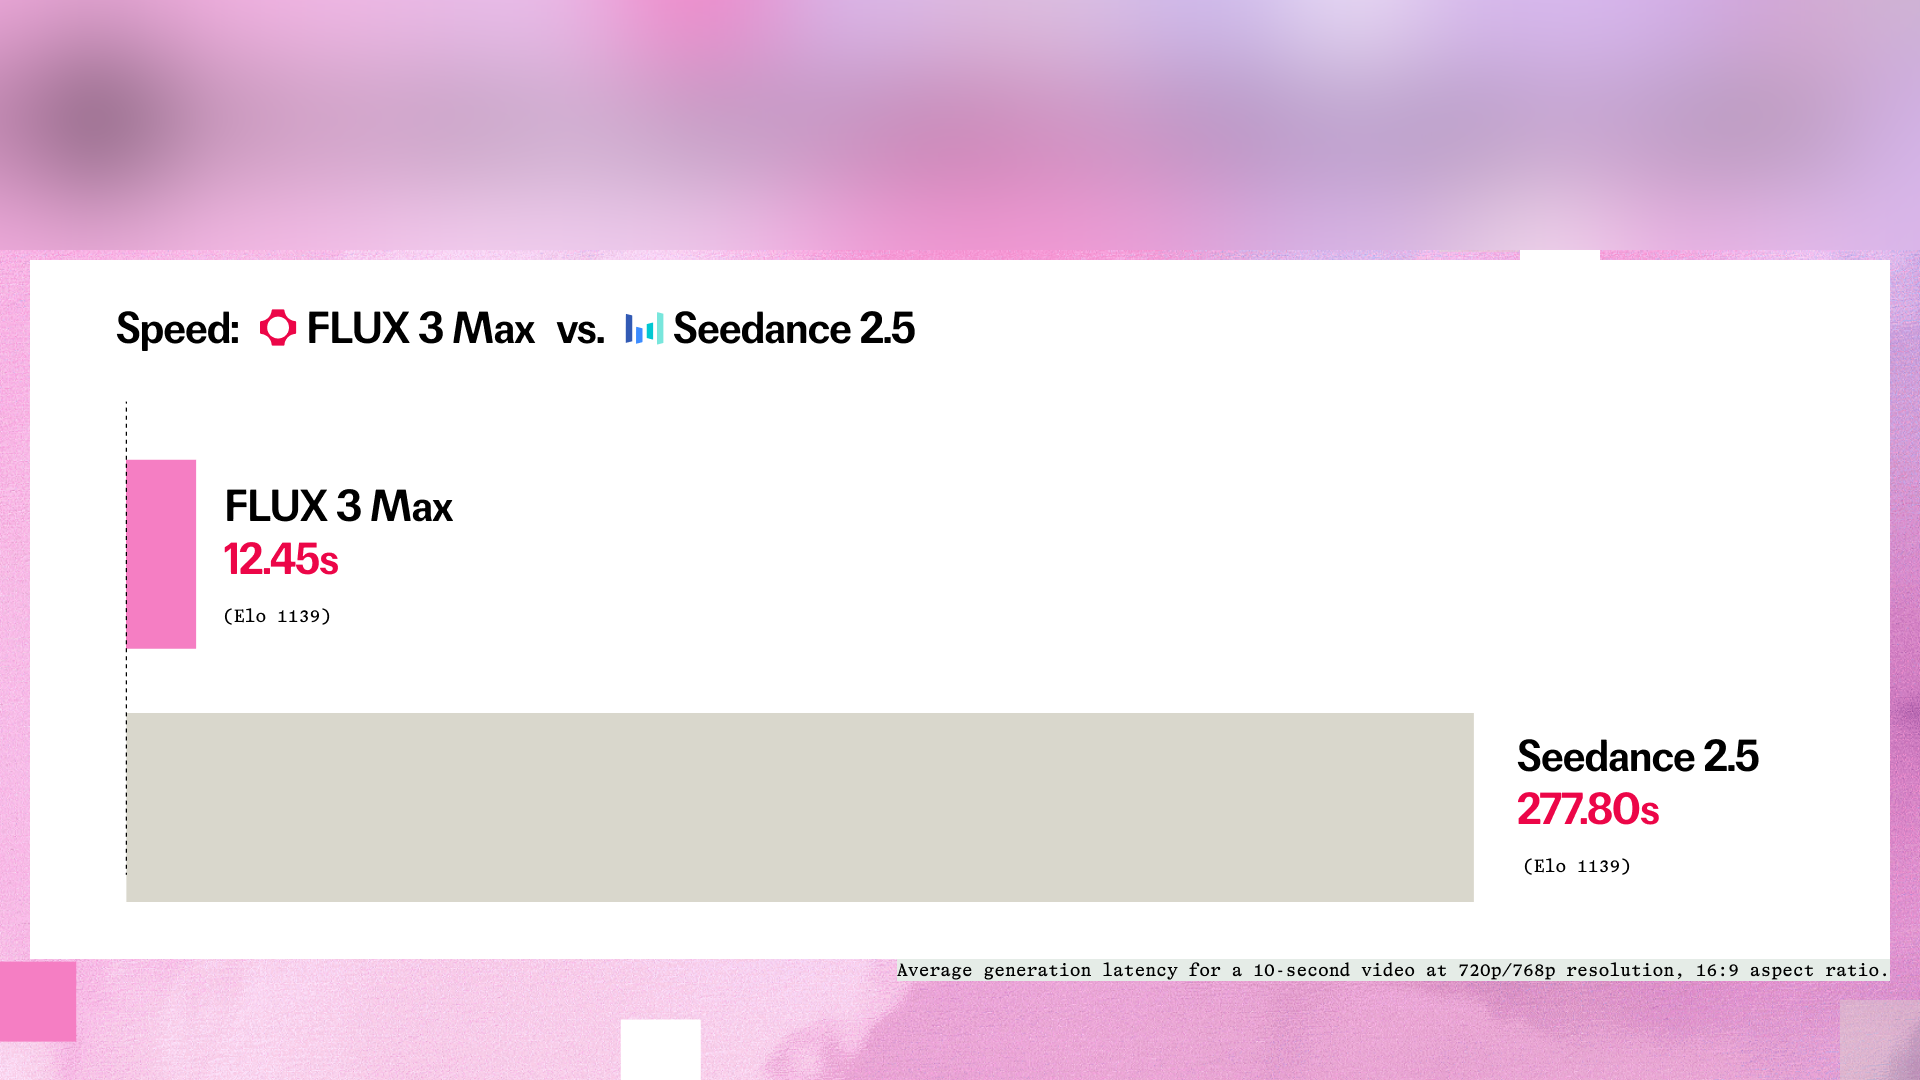 Videofal and Black Forest Labs
FLUX 3 Max
Video model post-trained by fal Research on FLUX 3, for text and image to video at 720p.
For film: A 10-second clip in about 12 seconds, so you can try many takes fast.
Maker's page ↗ -
LLMMiniMax
MiniMax M3.1 Flash
New Flash language model for agents and coding; MiniMax says nearly three times faster online and 70% cheaper to use.
Maker's page ↗
-

DeepSeek V4.1 Flash 1017
V4.1 Flash updated to version 1017, now behind the deepseek-flash API name, with weights on Hugging Face.
Maker's page ↗
-
FLUX 3 Image Klein
5.6B open-weights image model for text-to-image, editing and multi-reference with up to 10 images, native 4K.
For film: Runs locally on consumer GPUs, and bounding boxes place elements where you ask.
Maker's page ↗ -
VideoByteDance (BytePlus)
OmniHuman 2.0
Audio-driven avatar video from one image plus speech, music or dialogue, now on the BytePlus API.
For film: Lip movement and expression follow the audio, for talking and singing characters.
Maker's page ↗ -
Instant Soundtracks
Upload a video and get an original score plus sound effects placed on the timeline, in ElevenCreative and the API.
For film: Effects come as separate layers you can retime; the score can follow existing audio.
Maker's page ↗ -
 ImageKrea
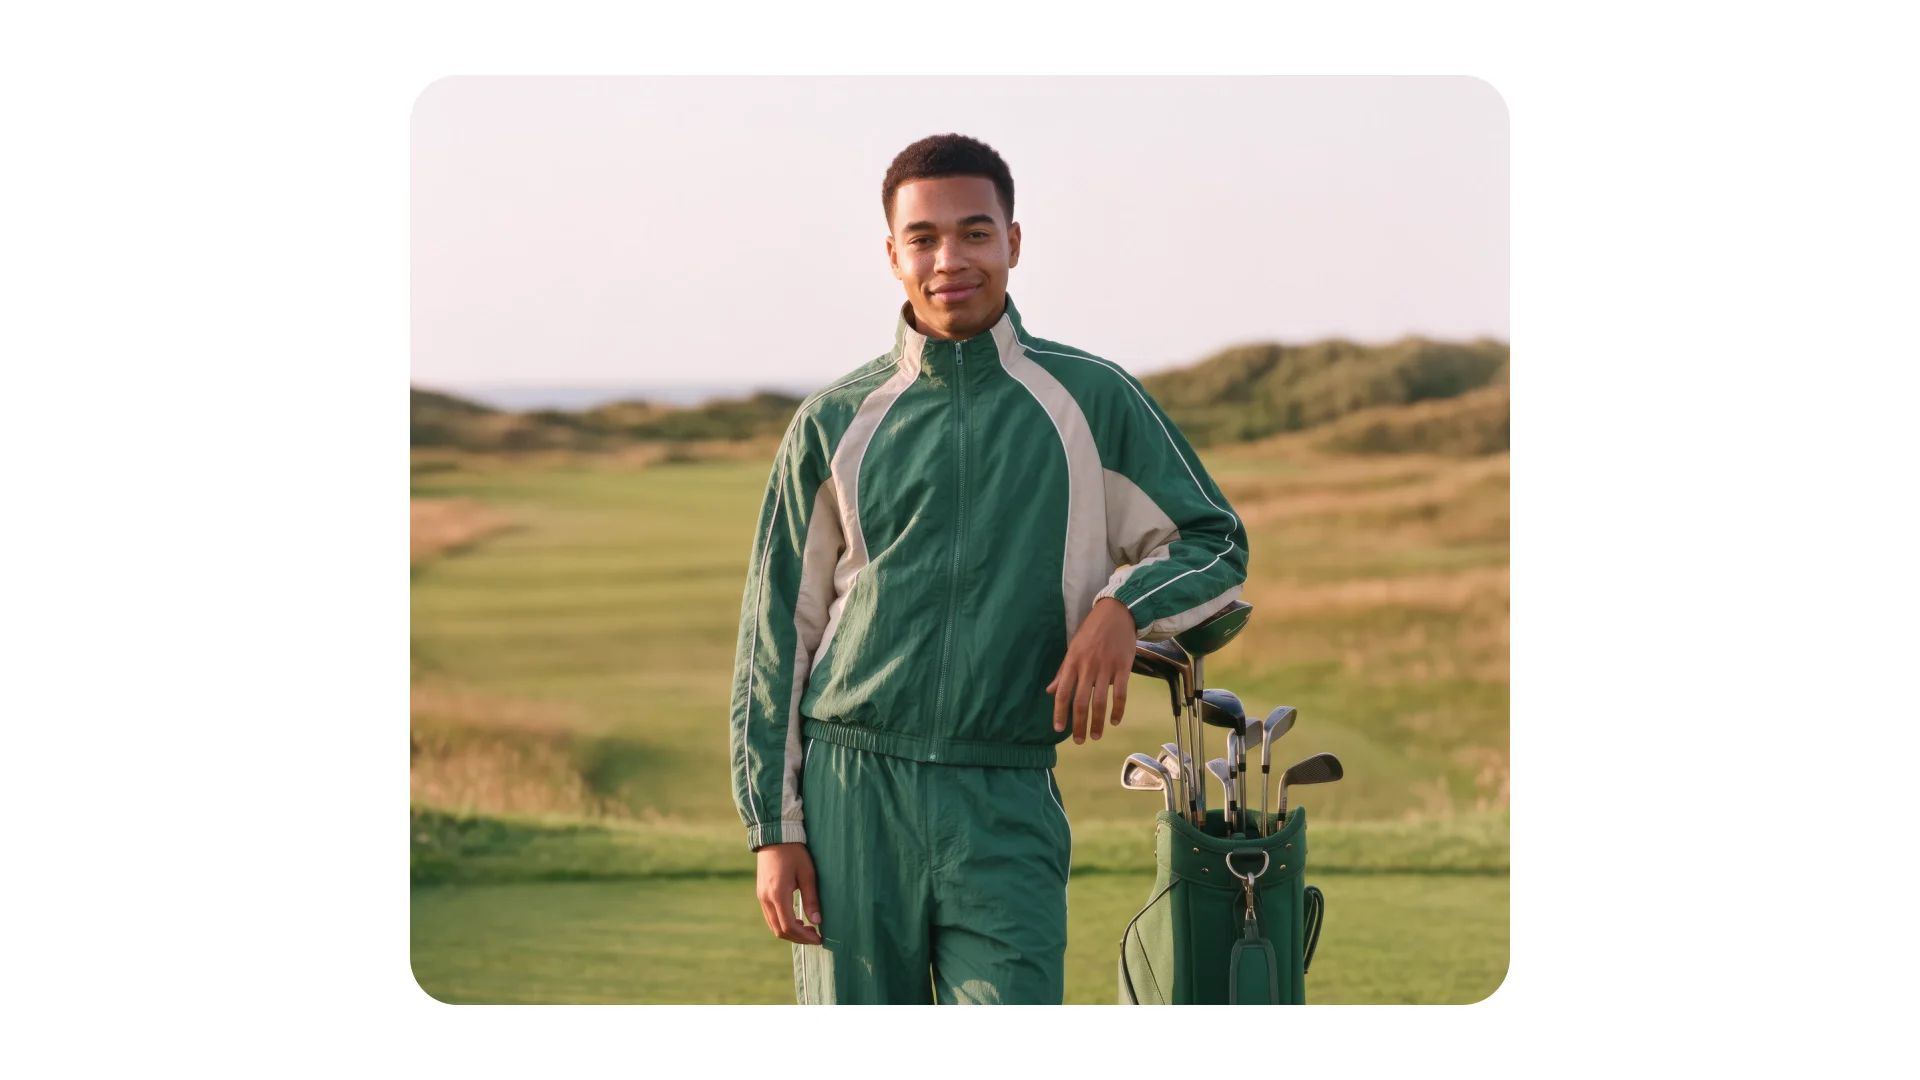
Krea 3
Krea's new image editing model: most edits under 8 seconds at native 2K, up to 6 reference images per edit.
For film: Keeps the same character across poses, locations and light for a consistent set.
Maker's page ↗ -
 VideoKuaishou
Kling 4.0
Open to everyone in the Kling app since 15 Oct: 3 to 30 second clips at 720p and 1080p, and Omni Reference with up to 15 references and 10 keyframes. 4K is listed but Kling's own 4.0 guide still marks it coming soon, and so is 10-bit HDR. Kling made the 4.0 API fully available on 28 Oct, at 720p and 1080p.
For film: Long single takes with keyframe control, now in the app and on the API.
Maker's page ↗ -
Muse Spark Open
Open-weight multimodal model, 816B total and 42B active, 1M-token context, built for coding and agentic work.
Maker's page ↗
-

HeyGen Voice
Voice cloning that turns a recording, a script and a target image into speech shaped for the scene on screen.
For film: Delivery and room acoustics match the shot, from studio to street to a moving car.
Maker's page ↗ -
Mirelo SFX 2.0
Video-to-sound model that replaces a clip's audio with synced effects, foley and ambience while keeping dialogue.
For film: Keeps dialogue while adding sound; Studio and API take clips up to 10 minutes.
Maker's page ↗ -
 AudioxAI
Grok Voice 3.0
xAI's new speech-to-speech model, live in the API at the same price as Grok Voice 2.0.
For film: Replies in under a second and handles pauses, turn-taking and interruptions naturally.
Maker's page ↗
-
Drama 3
Fish Audio's most emotive text-to-speech model, live on fish.audio, the Fish Audio app and the API.
For film: Follows direction: a whisper stays a whisper and a laugh lands where you put it.
Maker's page ↗ -
 LLMGoogle
Gemini 4 Argon
Google's frontier model now generally available in the Gemini API, AI Studio and the Gemini app for Pro and Ultra.
Maker's page ↗

-
VideoAlibaba
Wan 3.0 Prime
Faster Wan 3.0 video model in Model Studio: text, image, video and audio in; 480P to 1080P, up to 30 seconds.
For film: Text-to-video, first-last frame and reference video in one model, generated faster.
Maker's page ↗
-
 LLMAnthropic
Claude Haiku 5.5
Anthropic's fastest small model yet, around 75% cheaper to run than Haiku 4.5 on average.
Maker's page ↗ -
 VideoShengshu
Vidu Q4 Preview
Preview of the next Vidu model: image and reference-to-video with native audio, 3 to 16 second clips, 2K/4K out.
For film: Up to 15 image and 3 voice references, with multi-shot camera moves in one take.
Maker's page ↗
-
ImageGoogle DeepMind
Nano Banana 2.1
An upgrade to the Gemini image line for visual design, mask-based editing and subject consistency, listed for Gemini, AI Studio, the Gemini API and Google Flow.
For film: Mask edits and steadier subjects for boards and key art beside Flow.
Maker's page ↗
-
VideoUtopai Studios
Utopai X
Utopai Studios' text to video model with audio, built inside a working film and TV studio, launched with the new PAI production workspace that ties script, references and takes to each shot.
For film: Takes stay tied to the shot, so you compare versions, not rebuild briefs.
Maker's page ↗
-
 AudioElevenLabs
Eleven v4
ElevenLabs' new text to speech model, plus a low-latency v4 Turbo, with more emotional range, stronger voice cloning and 90+ languages. Live in ElevenCreative, ElevenAgents and the API.
For film: More emotional range for temp dialogue and voice-over drafts.
Maker's page ↗
-
AudioSuno
Suno v6
Suno's v6 music models, with v6-wild and v6-mini, adding more control over editing, mashups, sampling and lyric updates, and taking text, audio, image and video inputs.
For film: Video and image inputs, plus finer edits, for temp score drafts.
Maker's page ↗
No drop matches that.
Links only. Each line is confirmed on the maker's own page, blog, changelog, GitHub or Hugging Face org; no aggregators and no rumours.
Licence tags show what the maker's licence or terms said on the day we filed the line. They're not legal advice, so check the linked terms before you use a model for client work. No tag means we couldn't find a clear answer.