
Weekly roundup
AI model drops: FLUX 3 Max and Fibo 2.0
A quieter week than our first roundup. fal shipped a very quick video model on Monday, then on Tuesday Bria and Mistral put out models worth testing for stills and voice work. The rest was voice agents and language models, and they're listed at the bottom. We've also added one late catch from the week before.
FLUX 3 Max: a 10-second clip in about 12 seconds
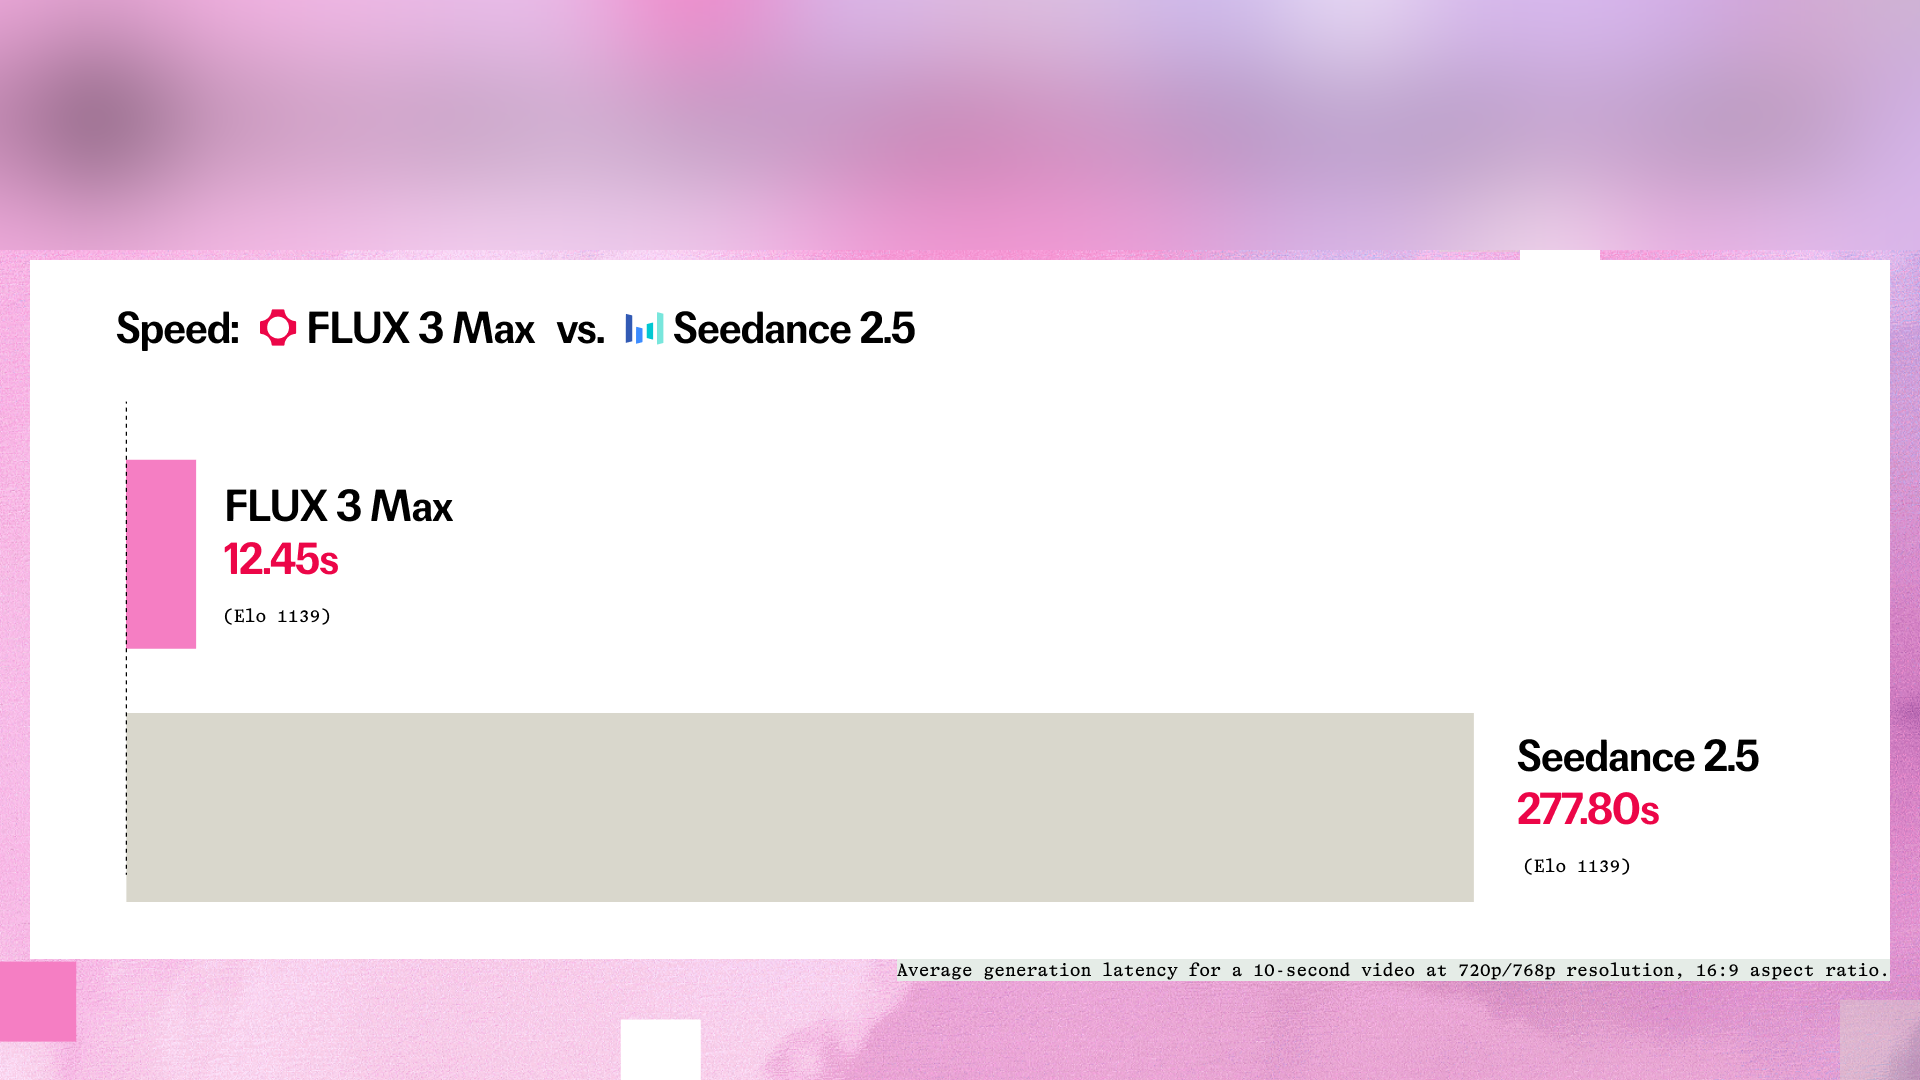
fal Research post-trained this one on Black Forest Labs' FLUX 3, and it does text-to-video and image-to-video at 720p. The pitch is speed: fal says a 10-second clip comes back in 12.45 seconds, against 277.80 for Seedance 2.5, with both on the same preliminary Artificial Analysis score. So you can try a pile of takes of one shot in the time a slower model gives you one, which is handy when you're still working out the framing. It's $0.0425 a second until 7 November, then the $0.17 list price applies, and there's a Model drops line with the link if you want to try it.
Fibo 2.0: generate and edit stills in one open model

Bria's Fibo 2.0 puts image generation and editing in one open-weights model, and edits are meant to leave alone what you didn't ask to change, like identity, layout and lighting. You can mask an area or give it up to 4 reference images, and because it's trained on structured captions that treat lighting, camera and depth of field as separate fields, you can change the time of day without the rest of the frame drifting. Bria says it's trained only on licensed data, and there's a faster Edit Turbo version for quick edits. The weights are non-commercial only, so a paid job needs a commercial agreement with Bria.
Voxtral 3: voices that change pace with the line

Mistral's new speech family includes Voxtral Mini TTS 3, with voices that adjust emotion, pace and emphasis to the context, in 35+ languages and 50+ dialects. Pro Voice can reproduce a speaker's character and emotional range from 30 minutes of audio, which is the part to try for scratch narration or temp lines in another language. On the listening side, Voxtral Small Transcribe 3 covers 50+ languages and tracks who said what, useful for logging interviews. You can use it through Mistral's EU-hosted API or run it on your own kit.
Grok Voice 3.0: a voice that answers back in under a second
xAI shipped this on 14 Oct and we only caught it on the 23rd, so it's late, but it's worth a look. It's a speech-to-speech model, so you talk and it talks back, and xAI says it replies in under a second and handles pauses, turn-taking and interruptions. That's the part to test if you want a live character for an installation or a stream, or a voice to run lines against that actually reacts. It's in xAI's Speech to Speech API at $0.08 a minute, and xAI's pages don't say clearly whether you can use the output commercially, so check their terms before it goes into a paid job.
Also dropped
- Eleven Realtime v1 ElevenLabs, 20 Oct 2026
New speech-to-speech models for voice agents: v1 Mini for natural chat at low cost, v1 Max for complex tasks. - MiniMax M3.1 Flash MiniMax, 19 Oct 2026
New Flash language model for agents and coding; MiniMax says nearly three times faster online and 70% cheaper to use. - DeepSeek V4.1 Flash 1017 DeepSeek, 17 Oct 2026
V4.1 Flash updated to version 1017, now behind the deepseek-flash API name, with weights on Hugging Face.
Related on AI Field Notes
- ElevenLabs: our model notes Model notes
- Film news, October 2026 News month
Every claim here comes from the maker's own page, linked above. Licence tags are what the maker's licence or terms said on the day we filed, not legal advice, so check the linked terms before client work. The full day-by-day list is on Model drops, and older roundups are in the weekly archive.